Anthropic has officially released Claude Haiku 5.5, marking one of the most substantial leaps in intelligence, agentic capability, and cost efficiency in foundation model history.
Historically, lightweight models like Haiku were relegated to basic categorization, quick summarization, and lightweight parsing tasks. Haiku 5.5 shatters that ceiling: it posts a 72.4% score on OSWorld 2.1 (computer use), outpaces GPT-6 Luna across multiple knowledge and coding benchmarks, and slashes input token pricing by 90% down to $0.10 per million tokens.
Below is our complete visual breakdown, evaluation analysis, and cost architecture review.
Visual Evaluations and Performance Curves
The following carousel details the official benchmark scorecard, effort-level scaling trajectories across computer use, knowledge tasks, and multidisciplinary reasoning, alongside the token pricing matrix:
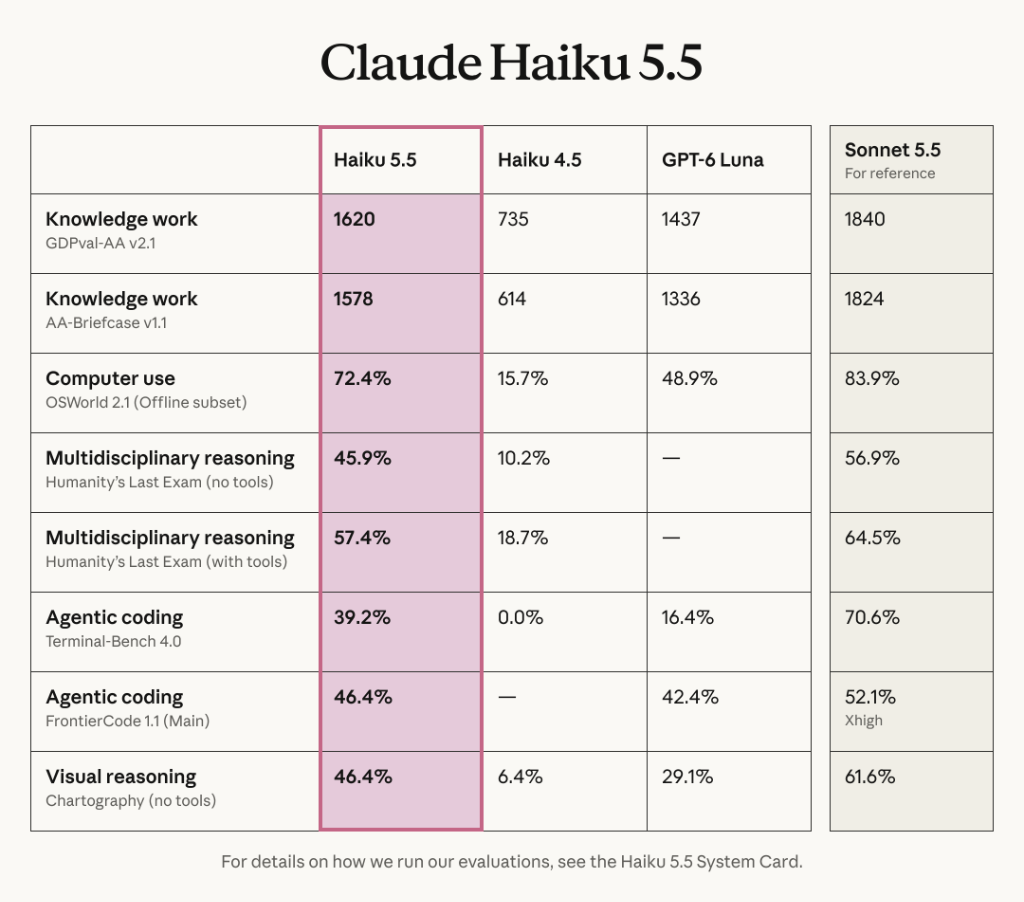
Claude Haiku 5.5 Benchmark Overview
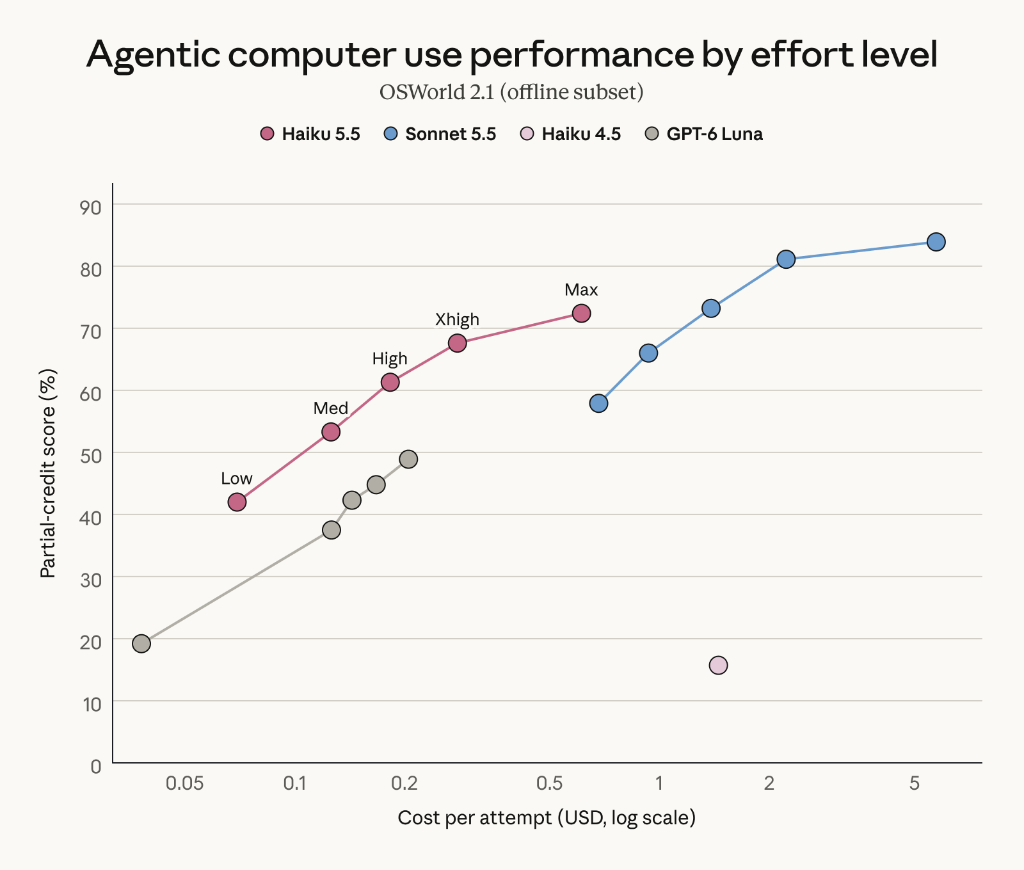
Agentic Computer Use Performance by Effort Level
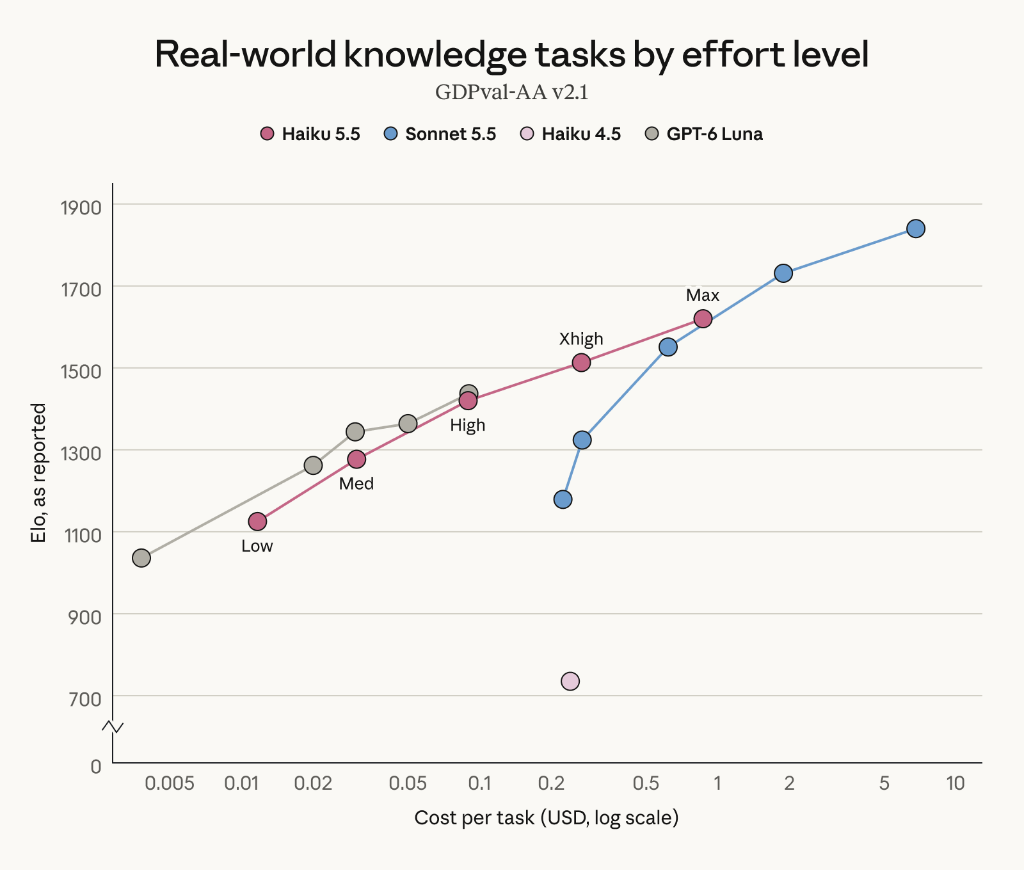
Real-World Knowledge Tasks by Effort Level
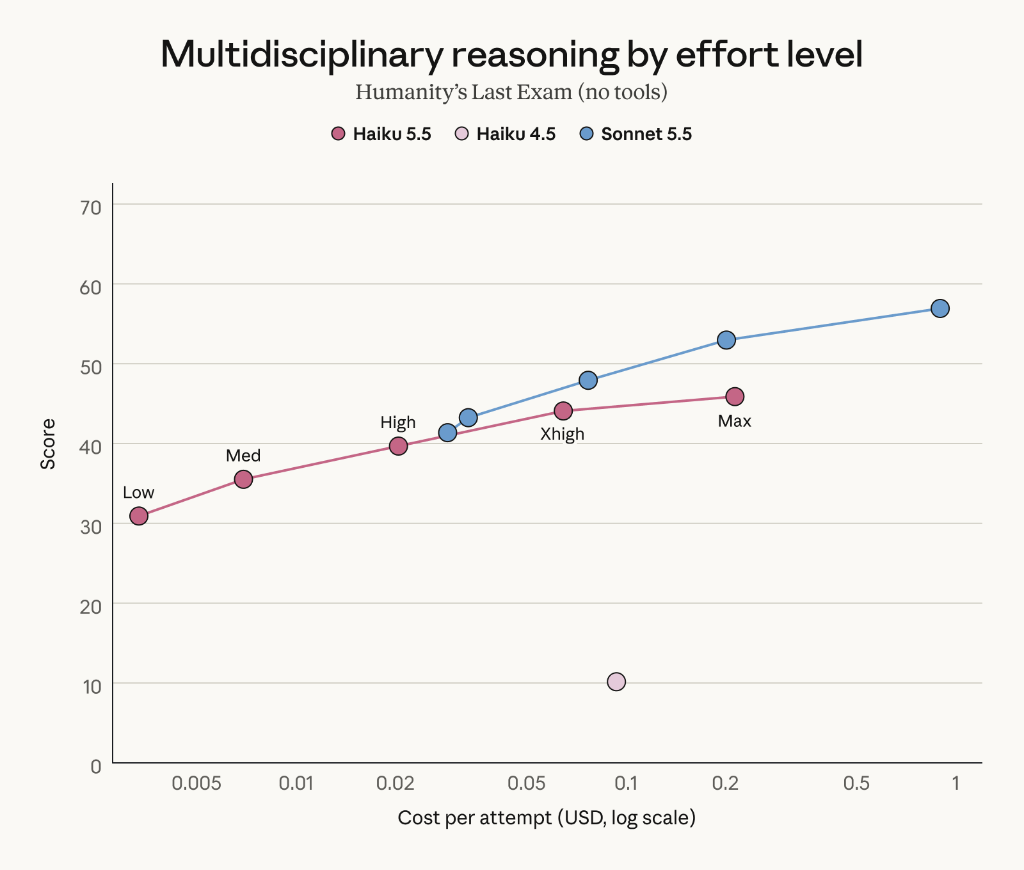
Multidisciplinary Reasoning by Effort Level
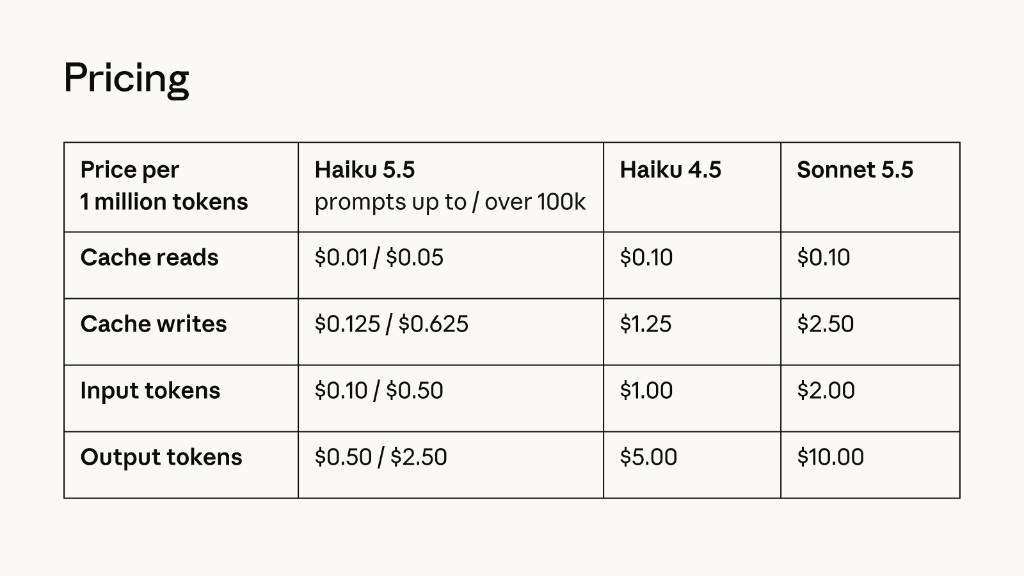
Token and Prompt Caching Pricing Comparison
Direct Benchmark Comparisons
Comparing Haiku 5.5 against its predecessor Haiku 4.5, competitor model GPT-6 Luna, and frontier reference Sonnet 5.5 reveals extraordinary gains across all critical domains:
| Evaluation Domain | Haiku 5.5 | Haiku 4.5 | GPT-6 Luna | Sonnet 5.5 (Ref) |
|---|---|---|---|---|
| Knowledge Work (GDPval-AA v2.1) | 1620 | 735 | 1437 | 1840 |
| Knowledge Work (AA-Briefcase v1.1) | 1578 | 614 | 1336 | 1824 |
| Computer Use (OSWorld 2.1 Offline) | 72.4% | 15.7% | 48.9% | 83.9% |
| Reasoning (Humanity's Last Exam, no tools) | 45.9% | 10.2% | - | 56.9% |
| Reasoning (Humanity's Last Exam, with tools) | 57.4% | 18.7% | - | 64.5% |
| Agentic Coding (Terminal-Bench 4.0) | 39.2% | 0.0% | 16.4% | 70.6% |
| Agentic Coding (FrontierCode 1.1) | 46.4% | - | 42.4% | 52.1% (Xhigh) |
| Visual Reasoning (Chartography, no tools) | 46.4% | 6.4% | 29.1% | 61.6% |
Several figures stand out immediately:
- OSWorld Computer Use (72.4% vs 15.7%): Haiku 4.5 achieved only 15.7% on OSWorld 2.1. Haiku 5.5 nearly quintuples that performance to 72.4%, dramatically beating GPT-6 Luna (48.9%) and approaching Sonnet 5.5 (83.9%).
- Terminal-Bench Agentic Coding (39.2% vs 0.0%): Haiku 4.5 was completely unable to complete Terminal-Bench 4.0 challenges. Haiku 5.5 hits 39.2%, demonstrating capable multi-step bash and CLI navigation.
- GDPval Knowledge Work (1620 vs 735 Elo): Haiku 5.5 gains more than 880 Elo points over Haiku 4.5, comfortably overtaking GPT-6 Luna (1437).
Dynamic Effort-Level Scaling
A defining feature of Haiku 5.5 is test-time effort scaling. Rather than running a monolithic fixed-compute inference path, developers can configure effort levels across five distinct presets: Low, Med, High, Xhigh, and Max.
- Agentic Computer Use: At Low effort, Haiku 5.5 scores ~42% at roughly $0.07 per attempt. Dialing compute to Max boosts the success rate to 72.4% at approximately $0.60 per attempt, remaining vastly cheaper than Sonnet 5.5 attempts.
- Knowledge Tasks (GDPval-AA): Scaling effort from Low (~1130 Elo at $0.012/task) to Max (1620 Elo at $0.85/task) allows applications to trade milliseconds and pennies for deep analytical rigor.
- Humanity's Last Exam: Multidisciplinary reasoning without external tools climbs smoothly from 31% (Low) to 45.9% (Max), providing predictable scaling characteristics for complex domain queries.
Radical Price Efficiency
While capabilities have surged, token pricing has plunged:
| Token Category | Haiku 5.5 (prompts <=100k) | Haiku 5.5 (prompts >100k) | Haiku 4.5 | Sonnet 5.5 |
|---|---|---|---|---|
| Cache reads | $0.01 / 1M | $0.05 / 1M | $0.10 / 1M | $0.10 / 1M |
| Cache writes | $0.125 / 1M | $0.625 / 1M | $1.25 / 1M | $2.50 / 1M |
| Input tokens | $0.10 / 1M | $0.50 / 1M | $1.00 / 1M | $2.00 / 1M |
| Output tokens | $0.50 / 1M | $2.50 / 1M | $5.00 / 1M | $10.00 / 1M |
For standard prompts up to 100k tokens, Haiku 5.5 costs $0.10 per million input tokens and $0.50 per million output tokens. Compared to Haiku 4.5 ($1.00 input / $5.00 output), this represents an immediate 90% reduction in API operational expense.
Prompt caching makes high-context agent execution even more compelling: cache reads cost a mere $0.01 per million tokens, meaning continuous state inspection during multi-step agent runs incurs negligible cost.
Summary and Availability
Claude Haiku 5.5 reshapes the design space for autonomous AI agents. Workflows that previously required costly frontier models can now execute reliably on Haiku 5.5 at a fraction of the budget.
To explore full specifications, pricing tiers, and alternative models, visit the listing on Prother:
- Explore the Claude Haiku 5.5 Tool Page
- Compare with Claude Opus 5.5
- Browse all models in the AI Models Directory


